

Every compute platform eventually separates state from compute, with the state layer capturing the durable economics. Web applications have databases, analytics have warehouses, and containers have persistent volumes. In each generation, compute commoditized and state compounded.
Inference has not had this moment. Every production serving stack treats its working state as scratch memory: evicted under pressure, lost on restart, unshared across replicas, and ungoverned by any system of record.
That working state is the Key-Value (KV) cache. During prefill, the model computes a key and value vector for each token, at every layer and every attention head. Those tensors are the model’s computed understanding of everything it has read. Its size grows linearly with sequence length and routinely exceeds the model weights themselves, up to hundreds of gigabytes per session. The cache is expensive to produce, reusable across requests, and shareable across users. But every production runtime discards it when the session ends.
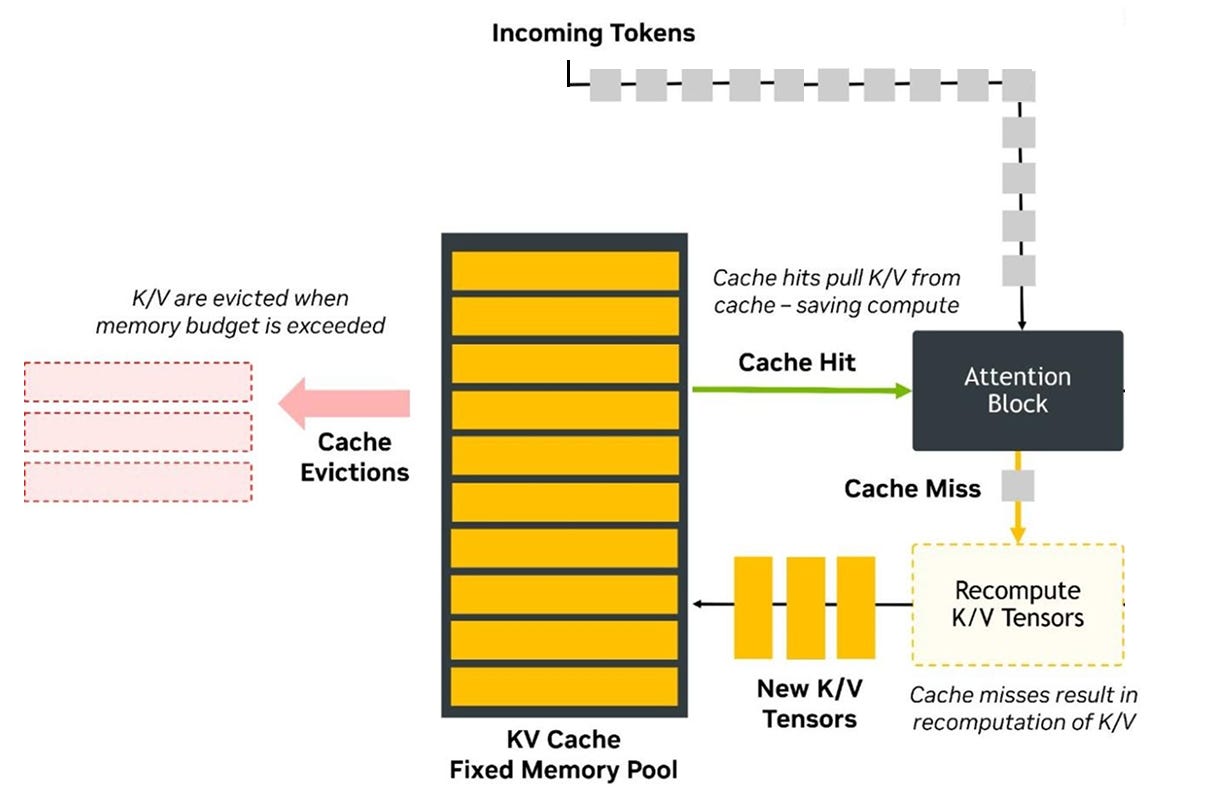
The industry’s solution to ever-growing context has been the “harness”: RAG, session history, summarization, and compaction. We think it is only half the picture. This is the distinction:
Harness-level memory operates in token space. It rewrites the model’s input and relies on the model to reconstruct the same understanding on every pass.
State-level memory operates in KV space. It preserves the understanding itself.
Token space is lossy in both directions. Preserve more tokens and the model uses them less efficiently.¹ Discard tokens and you lose important signal. The state was always the right store for context, but no one has built the system to persist it. Whoever becomes that system of record, treating KV context as a first-class data asset, inherits database economics at inference scale.
Why now
Ephemeral state was the correct engineering decision. The KV cache resides in GPU high-bandwidth memory (HBM), the scarcest resource in the datacenter. At 4K-token contexts, recomputing state costs less than moving it. Three forces have inverted that equation.
Context is exploding. Context windows have grown from 4K tokens (GPT-3, 2020) to 1M tokens (Claude Fable 5, 2026). Agentic workflows compound this: a coding agent might open a 100K-token repository, execute multiple tool calls with multi-thousand-token outputs, and produce conversation histories spanning hundreds of thousands of tokens per session. Multi-modal agents (video, robotics, world models) will especially inflate context by orders of magnitude beyond text.
Enterprises are taking control of their runtimes. Open-weight models like Kimi, DeepSeek, and GLM now deliver near-frontier performance at a fraction of frontier prices. Stripe cut inference costs 73% moving to self-hosted vLLM while serving the same 50 million daily calls on a third of the GPU fleet.² Self-hosting creates the customer for a state layer. The enterprise now controls the runtime and can build the durable, governed state layer that APIs never allowed.
The hardware layer is validating the tier. Jensen Huang told GTC Taipei that AI memory will force a complete revolution in storage.³ NVIDIA’s CMX on BlueField-4 is purpose-built silicon for moving KV cache off scarce GPU memory to cheaper tiers. VAST and WEKA ship storage products targeting the same workload.⁴ IBM Storage’s CTO now publicly argues that KV cache is “AI native data” requiring tiered management.⁵ But all of it is the physical tier that moves bytes. The governed, portable data layer above it remains open.
What the layer is worth
The case for a state layer rests on four independent arguments.
1. Cost of goods sold. Cache hit rate is to agents what Content Delivery Network (CDN) hit rate was to the web. The labs have already priced state reuse: Anthropic discounts cached input roughly 90%, DeepSeek 90%, OpenAI 50%.⁶ That pricing is public proof that reused state is worth an order of magnitude at the margin. For a self-hosted fleet, hit rate becomes the single largest controllable lever on agent unit economics.
2. Capacity. KV cache is the primary consumer of high-bandwidth memory, and HBM determines how many sessions each GPU can serve. In a multi-year GPU shortage, eliminating redundant prefill and tiering cold state off-device manufactures capacity that cannot otherwise be bought.
3. Capability. The ability to see and edit KV state opens up operations the harness cannot replicate. Start with branching. Teams already buy quality through test-time compute, sampling many reasoning paths and keeping the best, but every path pays for its own prefill. When the paths share one cached prefix, the tenth path costs little more than the first, and quality stops scaling with cost. The same access enables context steering, where a live correction or safety filter becomes a cache edit instead of a fine-tune or redeploy, and exact provenance, as the layer can trace the reasoning for an output. The largest unlock is organizational memory. Today context lives and dies inside a single session, so every agent re-derives its understanding of the same codebase, contracts, and knowledge base. A state layer computes that context once and every agent inherits it, so each session an agent runs makes every other agent in the company faster and cheaper.
4. Compliance. The KV cache is a mathematically derived copy of enterprise data. Shadow in the Cache and SpliceLeak proved the point by reconstructing private prompts token by token from shared caches. The cache inherits every obligation attached to the original text, including deletion rights and auditability. The practical defense in current runtimes is to restrict sharing and shorten cache lifetimes, trading away much of the savings that made the cache worth keeping. A layer with database-grade access control keeps the reuse economics and closes the attack surface.
The labs’ pricing sizes the market. If reused state avoids up to 90% of prefill compute, and prefill dominates an inference market projected to reach $1.3T, the state layer’s addressable revenue is a meaningful fraction of that.7
The Market
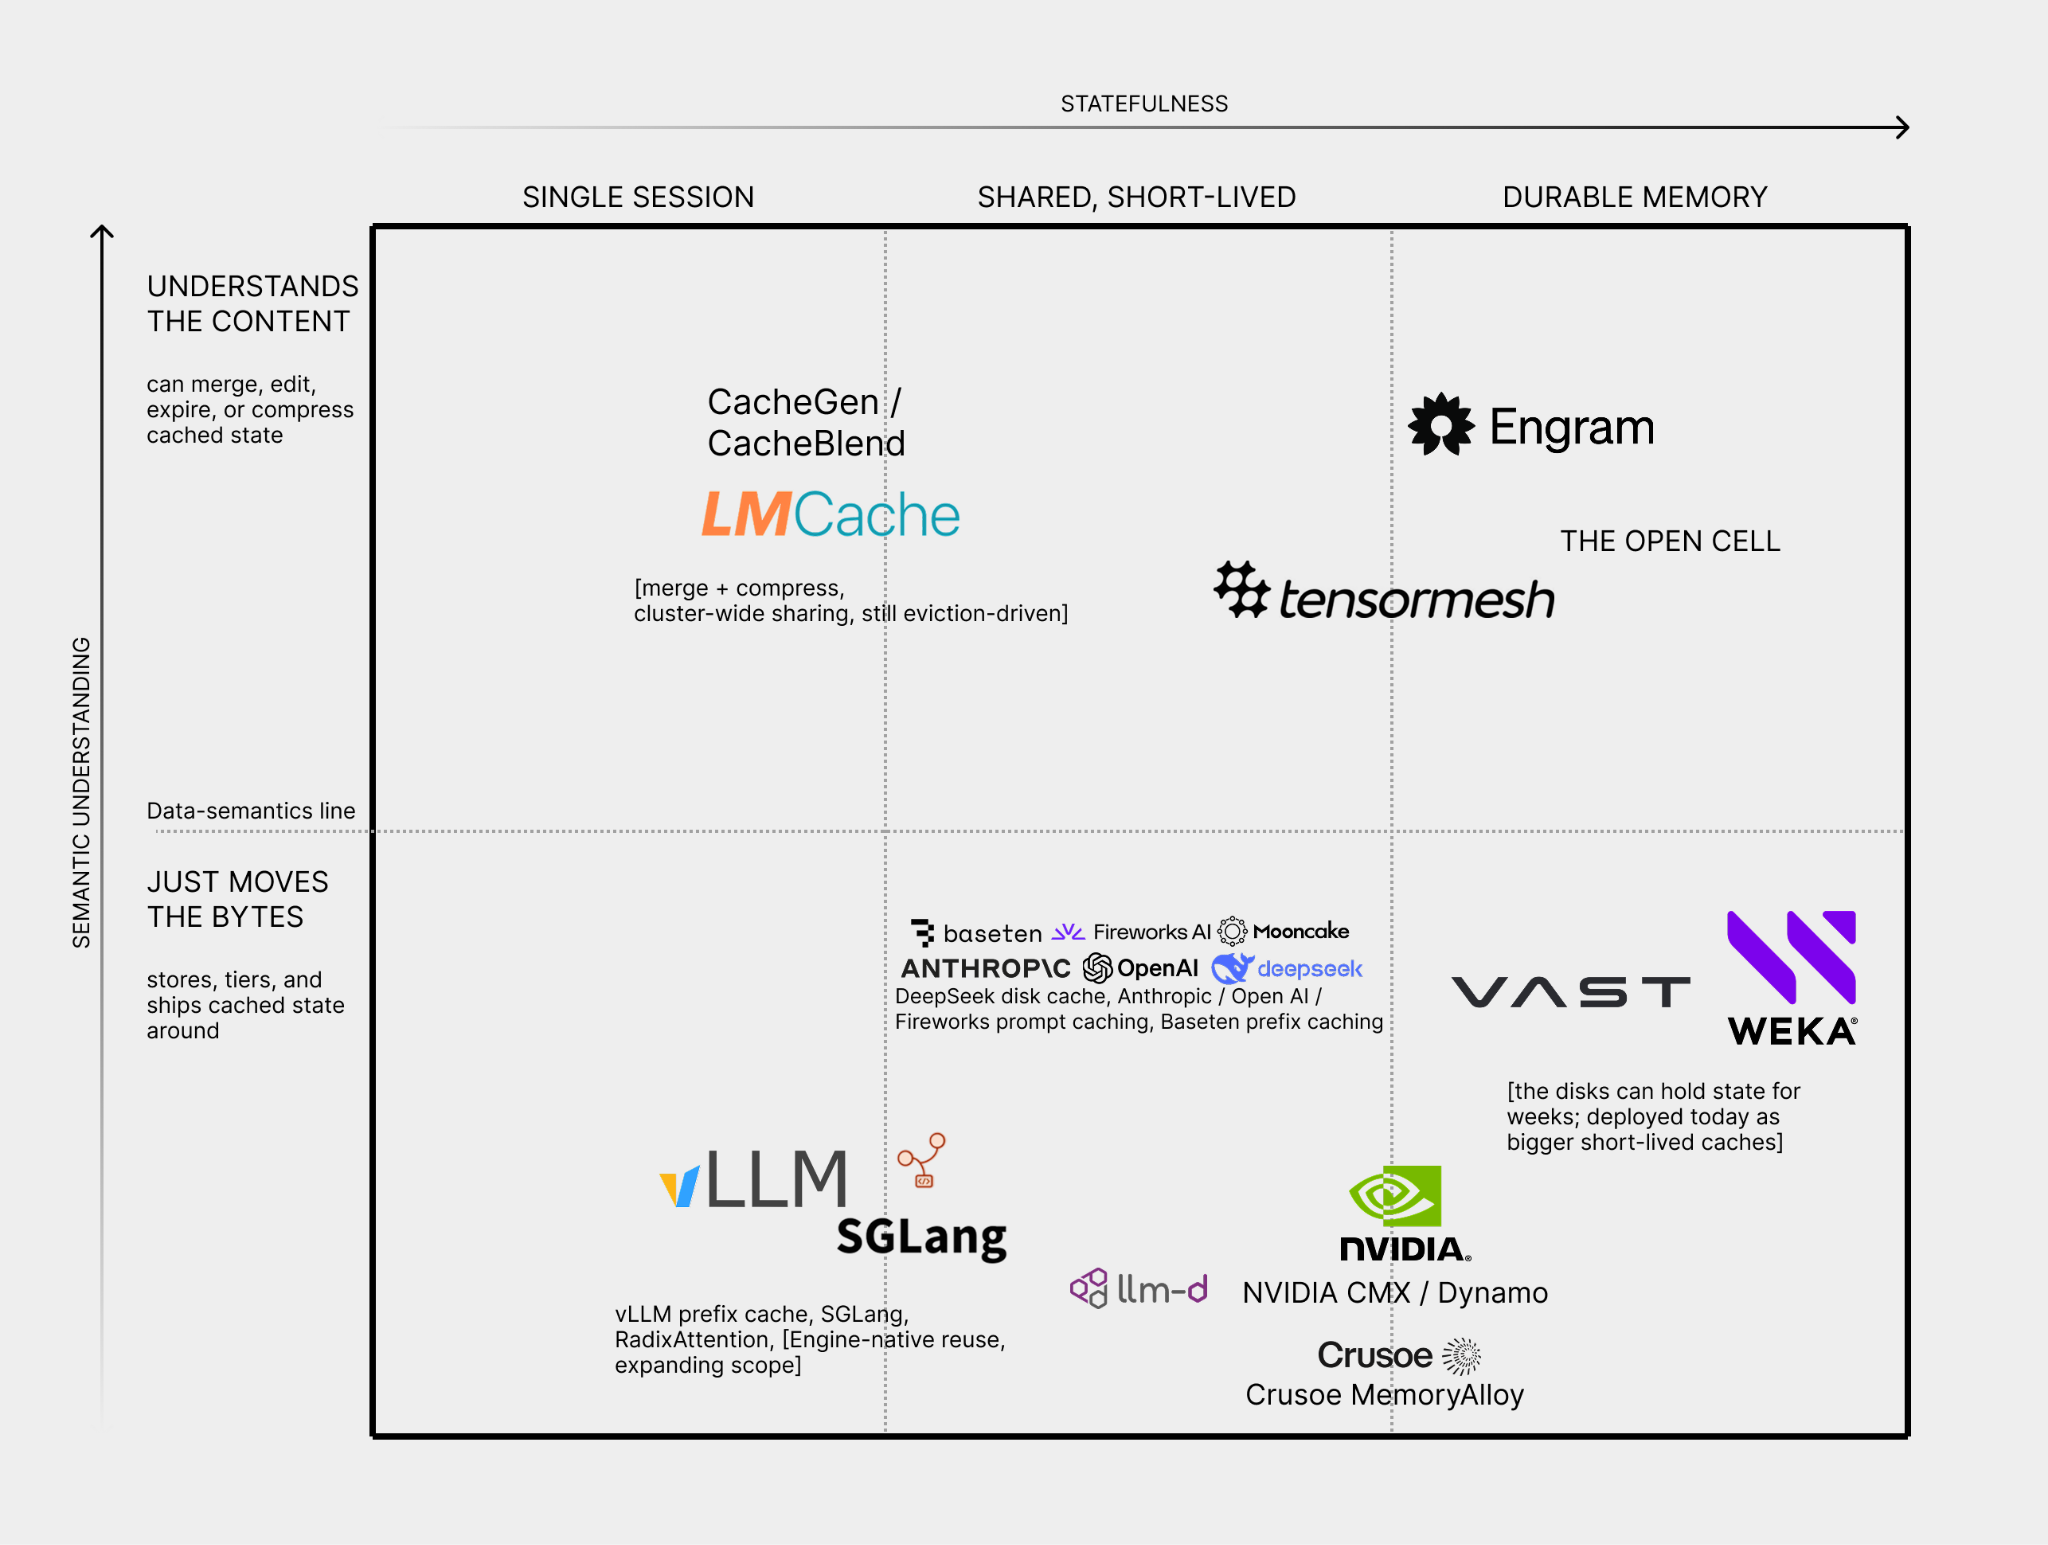
Extracting inference state from the engine is already proven, and most of the map is working on some piece of it. Below the semantics line, vLLM and SGLang ship engine-native prefix caching, the frontier labs and managed inference providers’ prompt caches share short-lived state across an org’s requests, and NVIDIA’s Dynamo, Crusoe’s MemoryAlloy, and the VAST and WEKA products tier cached state onto bigger, cheaper storage. Above the line sits the research lineage. vLLM ships a connector interface that lets an external system intercept, store, and re-inject KV state, which is how LMCache attaches. CacheGen showed KV state can be compressed and streamed over ordinary networks faster than the GPU can recompute it, and CacheBlend showed cached segments can be recombined into new prompts, making state shareable and composable.
What does not exist is the system of record. Every system on the map operates within one operator, one engine, one model version, and the state it holds remains an eviction-driven cache rather than a governed store. Tensormesh, founded by the LMCache creators, is the first company organized around that gap, and Engram attacks it from the parametric end. Two questions remain open: whether one neutral layer can span engines and model versions, and whether anyone can build the semantic operations that give stored state its potential.
The winner needs three things. Research depth in KV-state, since the core operations on cached state are still at the research frontier. Portability, through an interchange format that survives model upgrades and engine swaps. And engine-agnosticism from day one, so the layer can span the fragmented serving landscape.
How this plays out
Pricing power in infrastructure comes from one thing: how hard you are to replace. Everything below the semantics line is replaceable by construction: one prefix cache behaves like another, and storage tiers are interchangeable. Above the line, the layer holds context no one else has and orchestrates first-class operations on it: branching, steering, provenance, each requiring the layer to reason about what it holds. That is where value migrates. The labs rationally stopped at short-lived caches since they redeploy models weekly, so state dies with the model version. Enterprises are the opposite case. They freeze models for quarters. They carry deletion obligations. For them, the cache is too valuable to discard and too regulated to leave ungoverned.
Portability picks the winner. Today every engine swap or model upgrade wipes the cache, so state never accumulates. Once state survives those changes, it starts compounding across sessions, agents, and time. Enterprises will trade engines, hardware, and clouds to chase price and performance. They will not walk away from their accumulated state. Whoever holds it holds the customer.
For founders, the prize is larger than cheaper prefill. Over time, the state layer holds the work done on context, the corrections steered into it, the provenance linking answers to sources, the memory shared across agents. Re-running prefill rebuilds the raw tensors, but not the work. The KV cache is the most valuable dataset in the company’s AI stack, and today it lives inside runtimes that treat it as disposable.
Treat compute as fungible and focus on the state that compounds. That is the role of a system of record for inference.
Footnotes
1. Chroma, Context Rot. trychroma.com/research/context-rot
2. vLLM Production Deployment. https://introl.com/blog/vllm-production-deployment-inference-serving-architecture
3. Huang, GTC Taipei, June 2026
4. VAST: vastdata.com/blog/kvcache-context-memory-storage; WEKA via VentureBeat, Jan 2026
5. TechRadar, Vincent Hsu, https://www.techradar.com/pro/inference-needs-memory-how-context-is-becoming-ai-infrastructure
6. Pricing: docs.anthropic.com; platform.openai.com; api-docs.deepseek.com
7. Inference Market Size. https://finance.yahoo.com/technology/ai/articles/ai-infrastructure-market-shifting-inference-122000452.html